Google’s John Mueller Cautions Against Keyword-Rich Domains

Keyword-wealthy area names ended up the moment assumed to be an efficient way to maximize a website’s visibility and improve search engine rankings.

On the other hand, there are various good reasons why keyword-loaded domain names can be harmful to a website’s achievements.

In reaction to a thread on Reddit, Google Look for Advocate John Mueller shares his belief on domains with precise match keywords and phrases and why they may possibly be a terrible plan.

Mueller On Domains With Exact Match Keywords

In the r/Seo forum on Reddit, a person asks if it’s really worth it to spend a significant fee for a domain that contains the specific key phrases they want to rank for.

Mueller claims:

“I’m not a admirer of key word-key phrase domains, but YMMV. Random feelings:

everyone thinks you are a spammer

altering business concentration, or even growing, is more durable

you have no brand name, there’s nothing that persons can search for which “obviously” should really demonstrate your internet site. You are always competing, you are not setting up price with lengthy-time period customers.”

Mueller does not elaborate even more, but I’ll do my most effective to interpret his views in the adhering to sections.

1. Spam

Persons could possibly believe that a web-site with a keyword-wealthy domain title is connected with spam.

This is since spammers frequently use search term-prosperous domain names to manipulate search rankings and draw in unsuspecting website site visitors.

As a final result, a web site with a key word-wealthy domain title could be viewed as untrustworthy and unprofessional, which can travel absent potential consumers.

2. Enterprise Target

A search term-wealthy domain title can make it more durable to transform your business enterprise aim or develop your choices.

For instance, if a firm with a domain identify like “best-managing-shoes.com” decides to get started selling other athletic equipment, it can be complicated to influence shoppers that the site is a dependable resource for all those goods.

In distinction, a brand name identify area like “Nike.com” will allow the company to increase its offerings though keeping its manufacturer id.

3. No Manufacturer Title

A website with a search phrase-abundant domain name lacks a model name, which functions as a exclusive identifier to assistance buyers don’t forget and distinguish a business from its opponents.

A web-site can be very easily overlooked or confused with identical internet websites with out a brand title, harmful its popularity and consumer loyalty.

4. Absolutely nothing To Search For

A keyword-wealthy area title signifies there’s no company title for persons to lookup for.

When clients lookup for a business enterprise by title, they are much more probably to find and remember it than if they research for a generic search phrase like “running shoes.”

This usually means that a web page with a search term-loaded area title could wrestle to catch the attention of prolonged-phrase customers on the lookout for a specific company identify.

5. Constantly Competing

A web page with a key phrase-loaded area title generally competes with other web-sites with related keyword phrases.

In distinction, a internet site with a distinctive model title can build a faithful shopper foundation that returns to the web-site no matter of in which it appears in look for success.

In Summary

When key phrase-rich domain names may have after been witnessed as an powerful way to raise a website’s visibility, they can hurt its popularity and hinder its extended-time period achievements.

Developing a sound brand id with a one of a kind area identify can be additional efficient for making consumer loyalty and increasing your business.


Featured Image: Andrii Iemelianenko/Shutterstock

Source: Reddit

Google’s Expert Advice On SEO Troubleshooting With DevTools

Google has as soon as again shared its knowledge with the Web optimization and digital advertising communities by publishing a new installment of its Lightning Talks online video sequence on YouTube.

In the hottest movie, Google Developer Advocate Martin Splitt teaches viewers how to use Google Chrome DevTools to execute essential Search engine marketing troubleshooting techniques.

Splitt’s pro awareness and straightforward-to-follow guidelines make this movie an easy advice for any one with developer working experience hunting to optimize their website’s research motor rankings.

In this article are a handful of techniques to use Chrome DevTools to troubleshoot frequent Search engine marketing challenges on a staging website before it goes stay.

Utilizing The Cell-Helpful Examination

Working with the Cellular-Pleasant Take a look at in Google Look for Console is a terrific put to commence.

When you examination the URL of your staging surroundings, it will display you if there are any missing features in the rendered HTML.

If which is the circumstance, really don’t be concerned you can seem intently at what’s occurring by opening the internet site in your browser and applying Google Chrome DevTools.

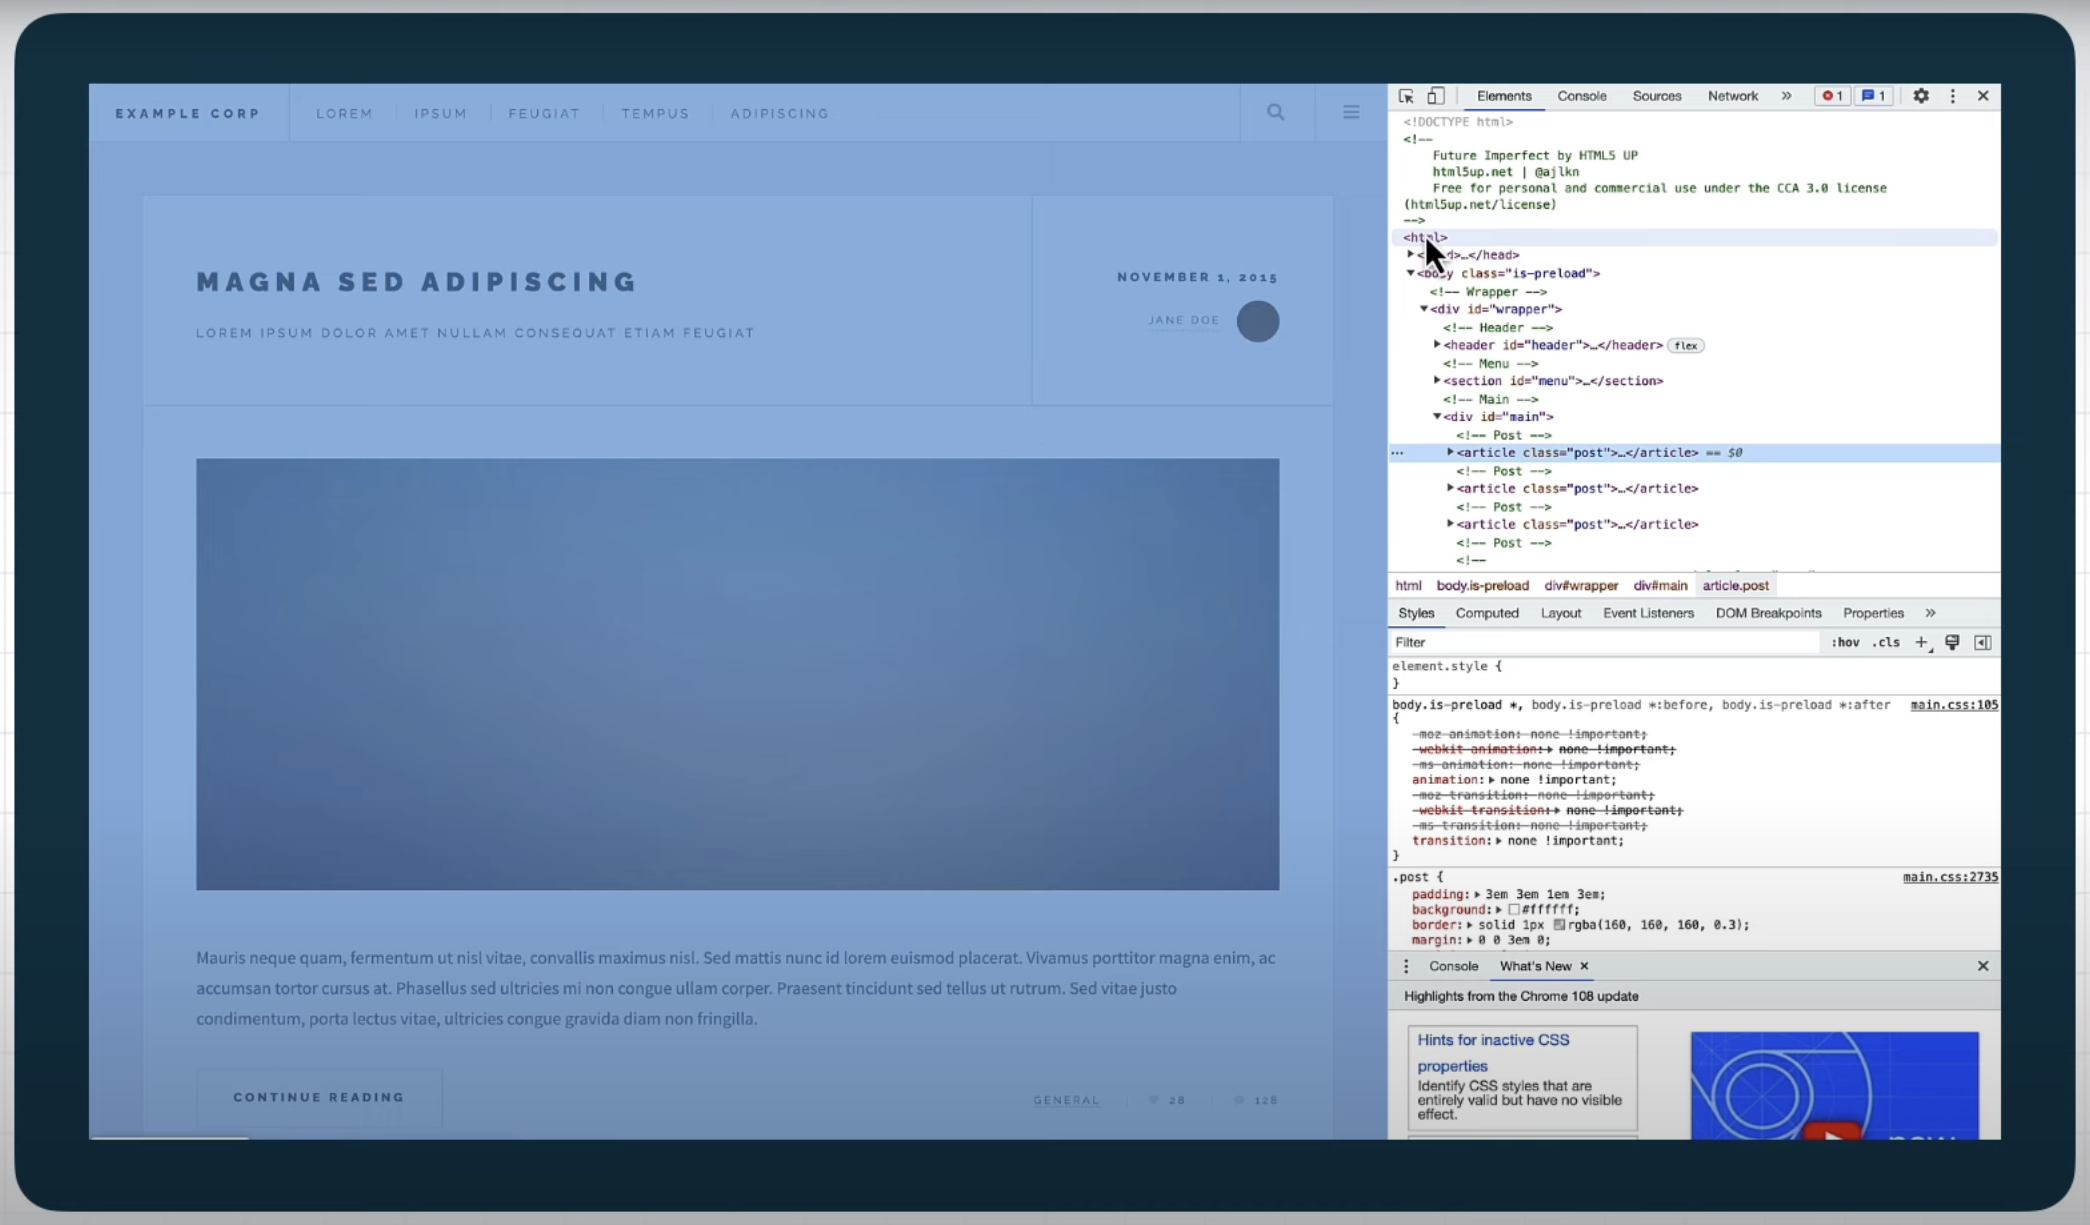
Applying The Elements Tab In DevTools

Google’s Expert Advice On SEO Troubleshooting With DevToolsScreenshot from: YouTube.com/GoogleSearchCentral, February 2023.

The Things tab in DevTools will give you an HTML representation of the page’s Doc Item Model (DOM).

This is a beneficial software for seeking for information on the website page and determining no matter if it is existing in the DOM.

If the material is missing in the rendered HTML, it will also be missing in the DOM.

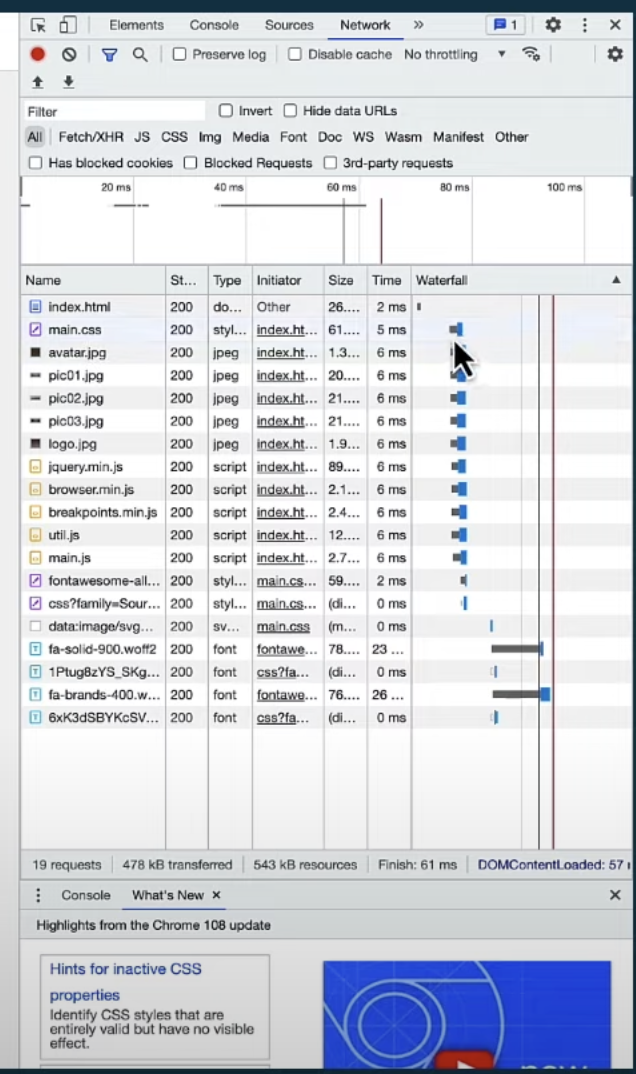
Utilizing The Network Tab

Google’s Expert Advice On SEO Troubleshooting With DevToolsScreenshot from: YouTube.com/GoogleSearchCentral, February 2023.

The Community tab in DevTools will allow you to see what is going on between the server and your browser.

When you reload the website page, you are going to be capable to see each individual request and response from the server.

The waterfall diagram will clearly show how long almost everything requires and wherever the time is spent.

You can also examine all requests and reaction headers, which can aid you glimpse for certain headers, these kinds of as the X-Robots header.

This can assistance determine whether or not the lacking content has designed its way from the server to the browser.

If the written content only appears after scrolling the site, you can use the Initiator tab to see what requested it.

This information and facts can then be employed to take care of the problem.

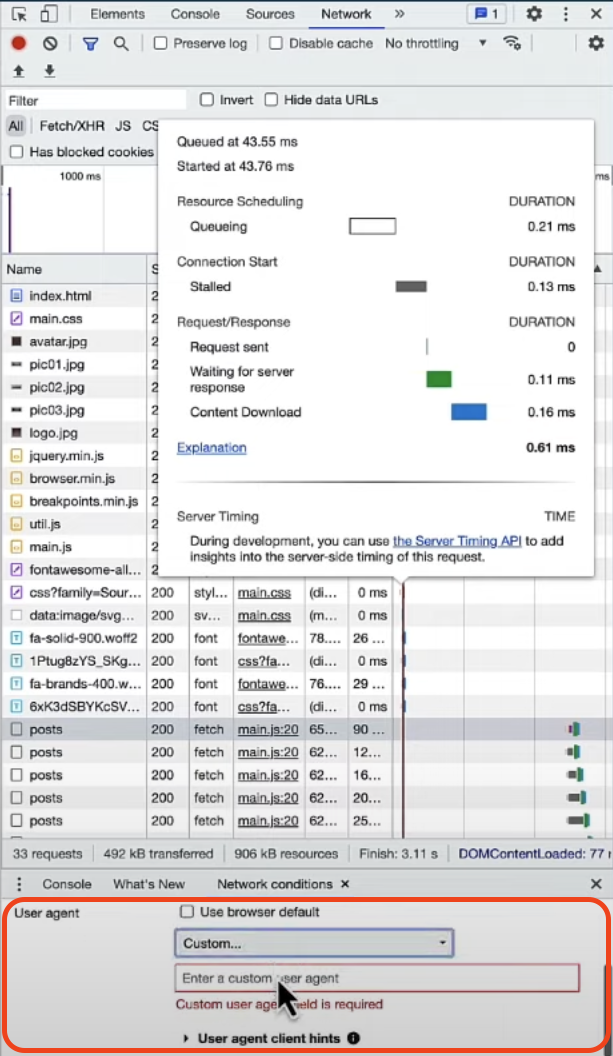
Placing Network Disorders

Google’s Expert Advice On SEO Troubleshooting With DevToolsScreenshot from: YouTube.com/GoogleSearchCentral, February 2023.

The Community tab in DevTools has other attributes, these as disabling the cache, environment the community transfer speed, and changing the consumer agent.

However, it is important to take note that environment the person agent to Googlebot may not produce the predicted success.

Googlebot also respects the robots.txt file, which your browser ignores, and some sites may do IP lookups to see if the request is coming from a Google info heart.

In conclusion, the browser’s Developer Resources offer a highly effective suite of debugging tools for Web optimization troubleshooting.

You can use the Factors Tab to inspect the DOM, the Community Tab to examine community requests and responses and set network problems these kinds of as caching and user agent.

You can promptly diagnose and resolve many Web optimization troubles by combining these with the testing instruments in Google Research Console.


Showcased Graphic: Screenshot from YouTube.com/GoogleSearchCentral, February 2023. 

Resource: YouTube

Meet Bard, Google’s Answer to ChatGPT

Google is not about to let Microsoft or any individual else make a swipe for its look for crown without having a fight. The firm declared nowadays that it will roll out a chatbot named Bard “in the coming months.” The launch seems to be a response to ChatGPT, the sensationally popular artificial intelligence chatbot produced by startup OpenAI with funding from Microsoft.

Sundar Pichai, Google’s CEO, wrote in a blog article that Bard is presently obtainable to “trusted testers” and built to set the “breadth of the world’s knowledge” guiding a conversational interface. It utilizes a smaller variation of a effective AI model known as LaMDA, which Google initial introduced in Might 2021 and is based mostly on comparable technological know-how to ChatGPT. Google says this will make it possible for it to supply the chatbot to more consumers and assemble suggestions to aid deal with worries around the quality and precision of the chatbot’s responses.

Google and OpenAI are the two making their bots on textual content generation software that, even though eloquent, is prone to fabrication and can replicate unsavory models of speech picked up on-line. The require to mitigate these flaws, and the point that this sort of software package are unable to effortlessly be current with new data, poses a problem for hopes of building powerful and rewarding new merchandise on leading of the technology, including the recommendation that chatbots could reinvent world-wide-web research.

Notably, Pichai did not announce designs to combine Bard into the search box that powers Google’s gains. Alternatively he showcased a novel, and careful, use of the underlying AI technological innovation to boost typical research. For inquiries for which there is no single agreed-on answer, Google will synthesize a reaction that displays the differing thoughts.

For example, the question “Is it a lot easier to master the piano or the guitar?” would be fulfilled with “Some say the piano is much easier to discover, as the finger and hand actions are more organic … Other individuals say that it is less difficult to learn chords on the guitar.” Pichai also reported that Google designs to make the fundamental technological know-how readily available to builders by an API, as OpenAI is performing with ChatGPT, but did not provide a timeline.

The heady exhilaration inspired by ChatGPT has led to speculation that Google faces a severe problem to the dominance of its web look for for the first time in many years. Microsoft, which recently invested about $10 billion in OpenAI, is holding a media occasion tomorrow relevant to its work with ChatGPT’s creator that is thought to relate to new attributes for the company’s next-put search motor, Bing. OpenAI’s CEO Sam Altman tweeted a photograph of himself with Microsoft CEO Satya Nadella soon after Google’s announcement.

Quietly released by OpenAI previous November, ChatGPT has developed into an online sensation. Its ability to reply sophisticated queries with obvious coherence and clarity has numerous customers dreaming of a revolution in education, business, and each day existence. But some AI experts recommend caution, noting that the instrument does not understand the information it serves up and is inherently vulnerable to creating issues up.  

The situation may be notably vexing to some of Google’s AI gurus, mainly because the company’s researchers designed some of the technologies guiding ChatGPT—a truth that Pichai alluded to in Google’s site put up. “We re-oriented the enterprise all around AI 6 yrs back,” Pichai wrote. “Since then we’ve ongoing to make investments in AI throughout the board.” He title-checked equally Google’s AI research division and operate at DeepMind, the Uk-primarily based AI startup that Google acquired in 2014.

ChatGPT is designed on top rated of GPT, an AI design acknowledged as a transformer initial invented at Google that normally takes a string of textual content and predicts what arrives future. OpenAI has attained prominence for publicly demonstrating how feeding enormous amounts of information into transformer styles and ramping up the computer electrical power running them can create methods adept at generating language or imagery. ChatGPT enhances on GPT by having individuals provide opinions to diverse responses to an additional AI product that good-tunes the output. 

Google has, by its possess admission, chosen to carry on cautiously when it will come to including the technological innovation behind LaMDA to products. Besides hallucinating incorrect information and facts, AI types experienced on textual content scraped from the Web are prone to exhibiting racial and gender biases and repeating hateful language.

Those limitations have been highlighted by Google scientists in a 2020 draft analysis paper arguing for warning with text technology engineering that irked some executives and led to the company firing two notable ethical AI scientists, Timnit Gebru and Margaret Mitchell.

Other Google researchers who labored on the technology powering LaMDA grew to become disappointed by Google’s hesitancy, and still left the firm to make startups harnessing the exact same engineering. The arrival of ChatGPT appears to have influenced the organization to accelerate its timeline for pushing text technology capabilities into its solutions.

What is SEO? Reverse Engineering Google’s AI (2022)

Search Engine Optimization (SEO) is the process of optimizing on-page and off-page factors that impact how high a web page ranks for a specific search term. This is a multi-faceted process that includes optimizing page loading speed, generating a link building strategy, as well as learning how to reverse engineer Google’s AI by using computational thinking.

Computational thinking is an advanced type of analysis and problem-solving technique that computer programmers use when writing code and algorithms. Computational thinkers will seek the ground truth by breaking down a problem and analyzing it using first principles thinking.

Since Google does not release their secret sauce to anyone, we will rely on computational thinking. We will walk through some pivotal moments in Google’s history that shaped the algorithms that are used, and we will learn why this matters.

How to Create a Mind

We will begin with a book that was published in 2012, called “How to Create a Mind: The Secret of Human Thought Revealed” by renowned futurist, and inventor Ray Kurzweil. This book dissected the human brain, and broke down the ways it works. We learn from the ground up how the brain trains itself using pattern recognition to become a prediction machine, always working at predicting the future, even predicting the next word.

How do humans recognize patterns in every day life? How are these connections formed in the brain? The book begins with understanding hierarchical thinking, this is understanding a structure that is composed of diverse elements that are arranged in a pattern, this arrangement then represents a symbol such as a letter or character, and then this is further arranged into a more advanced pattern such as a word, and eventually a sentence. Eventually these patterns form ideas, and these ideas are transformed into the products that humans are responsible for building.

By emulating the human brain, revealed is a pathway to creating an advanced AI beyond the current capabilities of the neural networks that were around at the time of publishing.

The book was a blueprint for creating an AI that can scale by vacuuming the world’s data, and use its multi-layered pattern recognition processing to parse text, images, audio, and video. A system optimized for upscaling due to the benefits of the cloud and its parallel processing capabilities. In other words there would be no maximum on data input or output.

This book was so pivotal that soon after its publishing the author Ray Kurzweil was hired by Google to become the Director of Engineering focused on machine learning and language processing. A role that perfectly aligned with the book he had written.

It would be impossible to deny how influential this book was to the future of Google, and how they rank websites. This AI book should be mandatory reading for anyone who wishes to become an SEO expert.

DeepMind

Launched in 2010, DeepMind was a hot new startup using a revolutionary new type of AI algorithm that was taking the world by storm, it was called reinforcement learning. DeepMind described it best as:

“We present the first deep learning model to successfully learn control policies directly from high-dimensional sensory input using reinforcement learning. The model is a convolutional neural network, trained with a variant of Q-learning, whose input is raw pixels and whose output is a value function estimating future rewards.”

By fusing deep learning with reinforcement learning it became a deep reinforcement learning system. By 2013, DeepMind was using these algorithms to rack up victories against human players on Atari 2600 games – And this was achieved by mimicking the human brain and how it learns from training and repetition.

Similar to how a human learns by repetition, whether it is kicking a ball, or playing Tetris, the AI would also learn. The AI’s neural network tracked performance and would incrementally self-improve resulting in stronger move selection in the next iteration.

DeepMind was so dominant in its technological lead that Google had to buy access to the technology. DeepMind was acquired for more than $500 million in 2014.

After the acquisition the AI industry witnessed successive breakthroughs, a type not seen since May 11, 1997, when chess grandmaster Garry Kasparov lost the first game of a six-game match against Deep Blue, a chess-playing computer developed by scientists at IBM. 

In 2015, DeepMind refined the algorithm to test it on Atari’s suite of 49 games, and the machine beat human performance on 23 of them.

That was just the beginning, later in 2015 DeepMind began focusing on AlphaGo, a program with the stated aim of defeating a professional Go World Champion. The ancient game of Go, which was first seen in China some 4000 years ago, is considered to be the most challenging game in human history, with its potential 10360 possible moves.

DeepMind used supervised learning to train the AlphaGo system by learning from human players. Soon after, DeepMind made headlines after AlphaGo beat Lee Sedol, the world champion, in a five-game match in March 2016.

Not be outdone, in October, 2017 DeepMind released AlphaGo Zero, a new model with the key differentiator that it required zero human training. Since it did not require human training, it also required no labeling of data, the system essentially used unsupervised learning. AlphaGo Zero rapidly surpassed its predecessor, as described by DeepMind.

“Previous versions of AlphaGo initially trained on thousands of human amateur and professional games to learn how to play Go. AlphaGo Zero skips this step and learns to play simply by playing games against itself, starting from completely random play. In doing so, it quickly surpassed human level of play and defeated the previously published champion-defeating version of AlphaGo by 100 games to 0.”

In the meantime, the SEO world was hyper focused on PageRank, the backbone of Google. It begins in 1995, when Larry Page and Sergey Brin were Ph.D. students at Stanford University. The duo began collaborating on a novel research project nicknamed “BackRub”. The goal was ranking web pages into a measure of importance by converting their backlink data. A backlink is quite simply any link from one page to another, similar to this link.

The algorithm was later renamed to PageRank, named after both the term “web page” and co-founder Larry Page. Larry Page and Sergey Brin had the ambitious goal of building a search engine that could power the entire web purely by backlinks.

And it worked.

PageRank Dominates Headlines

SEO professionals immediately understood the basics of how google calculates a quality ranking for a web page by using PageRank. Some Savvy black hat SEO entrepreneurs took it a step further, understanding that to scale content, that it might make sense to buy links instead of waiting to acquire them organically.

A new economy emerged around backlinks. Eager website owners who needed to impact search engine rankings would buy links, and in return desperate to monetize websites would sell them links.

The websites who purchased links often overnight invaded Google outranking established brands.

Ranking using this method worked really well for a long time – Until it stopped working, probably around the same time machine learning kicked in and solved the underlying problem.  With the introduction of deep reinforcement learning, PageRank would become a ranking variable, not the dominant factor.

By now the SEO community is divided on link buying as a strategy. I personally believe that link buying offers sub-optimal results, and that the best methods to acquire backlinks is based on variables that are industry specific. One legitimate service that I can recommend is called HARO (Help a Reporter Out). The opportunity at HARO is to acquire backlinks by fulfilling media requests.

Established brands never had to worry about sourcing links, since they had the benefits of time working in their favor. The older a website, the more time it has had to collect high quality backlinks. In other words, a search engine ranking was heavily dependent on the age of a website, if you calculate using the metric time = backlinks.

For example, CNN would naturally receive backlinks for a news article due to its brand, its trust, and because it was listed high to begin with – So naturally it gained more backlinks from people researching an article and linking to the first search result they found.

Meaning that higher ranked webpages organically received more backlinks. Unfortunately, this meant new websites  were often forced to abuse the backlink algorithm by turning to a backlink marketplace.

In the early 2000s, buying backlinks worked remarkably well and it was a simple process. Link buyers purchased links from high authority websites, often sitewide footer links, or perhaps on a per article basis (often disguised as a guest post), and the sellers desperate to monetize their websites were happy to oblige – Unfortunately, often at the sacrifice of quality.

Eventually the Google talent pool of machine learning engineers understood that coding search engine results by hand was futile, and a lot of PageRank was handwritten coding. Instead they understood that the AI would eventually become responsible with fully calculating the rankings with no to little human interference.

To stay competitive Google uses every tool in their arsenal and this includes deep reinforcement learning – The most advanced type of machine learning algorithm in the world.

This system layered on top of Google’s acquisition of MetaWeb was a gamechanger. The reason the 2010 MetaWeb acquisition was so important is that it reduced the weight that Google placed on keywords. Context was all of a sudden important, this was achieved by using a categorization methodology called ‘entities’. As Fast Company described:

Once Metaweb figures out to which entity you’re referring, it can provide a set of results. It can even combine entities for more complex searches– “actresses over 40” might be one entity, “actresses living in New York City” might be another, and “actresses with a movie currently playing” might be another. “.

This technology was rolled into a major algorithm update called RankBrain that was launched in the spring of 2015. RankBrain focused on understanding context versus being purely keyword based, and RankBrain would also consider environmental contexts (e.g., searcher location) and extrapolate meaning where there had been none before. This was an important update especially for mobile users.

Now that we understand how Google uses these technologies, let’s use computational theory to speculate on how it’s done.

What is Deep Learning?

Deep learning is the most commonly used type of machine learning – It would be impossible for Google not to use this algorithm.

Deep learning is influenced significantly by how the human brain operates and it attempts to mirror the brain’s behavior in how it uses pattern recognition to identify, and categorize objects.

For example, if you see the letter a, your brain automatically recognizes the lines and shapes to then identify it as the letter a. The same is applied by the letters ap, your brain automatically attempts to predict the future by coming up with potential words such as app or apple. Other patterns may include numbers, road signs, or identifying a loved one in a crowded airport.

You can think of the interconnections in a deep learning system to be similar to how the human brain operates with the connection of neurons and synapses.

Deep learning is ultimately the term given to machine learning architectures that join many multilayer perceptron’s together, so that there isn’t just one hidden layer but many hidden layers. The “deeper” that the deep neural network is, the more sophisticated patterns the network can learn.

Fully connected networks can be combined with other machine learning functions to create different deep learning architectures.

How Google Uses Deep Learning

Google spiders the world’s websites by following hyperlinks (think neurons) that connect websites to one another. This was the original methodology that Google used from day one, and is still in use. Once websites are indexed various types of AI are used to analyze this treasure trove of data.

Google’s system labels the webpages according to various internal metrics, with only minor human input or intervention. An example of an intervention would be the manual removal of a specific URL due to a DMCA Removal Request.

Google engineers are renowned for frustrating attendees at SEO conferences, and this is because Google executives can never properly articulate how Google operates. When questions are asked about why certain websites fail to rank, it’s almost always the same poorly articulated response. The response is so frequent that often attendees preemptively state that they have committed to creating good content for months or even years on end with no positive results.

Predictably, website owners are instructed to focus on building valuable content – An important component, but far from being comprehensive.

This lack of answer is because the executives are incapable of properly answering the question. Google’s algorithm operates in a black box. There’s input, and then output – and that is how deep learning works.

Let’s now return to a ranking penalty that is negatively impacting millions of websites often without the knowledge of the website owner.

PageSpeed Insights

Google is not often transparent, PageSpeed Insights is the exception. Websites that fail this speed test will be sent into a penalty box for loading slowly – Especially if mobile users are impacted.

What is suspected is that at some point in the process there’s a decision tree that parses fast websites, versus slow loading (PageSpeed Insights failed) websites. A decision tree is essentially an algorithmic approach which splits the dataset into individual data points based on different criteria. The criteria may be to negatively influence how high a page ranks for mobile versus desktop users.

Hypothetically a penalty could be applied to the natural ranking score. For example, a website that without penalty would rank at #5 may have a -20, -50, or some other unknown variable that will reduce the rank to #25, #55, or another number as selected by the AI.

In the future we may see the end of the PageSpeed Insights, when Google becomes more confident in their AI. This current intervention on speed by Google is dangerous as it may potentially eliminate results that would have been optimal, and it discriminates against the less tech savvy.

It’s a big request to demand that everyone who runs a small business to have the expertise to successfully diagnose and remedy speed test issues. One simple solution would be for Google to simply release a speed optimization plug-in for wordpress users, as wordpress powers 43{4224f0a76978c4d6828175c7edfc499fc862aa95a2f708cd5006c57745b2aaca} of the internet.

Unfortunately, all SEO efforts are in vain if a website fails to pass Google’s PageSpeed Insights. The stakes are nothing less than a website vanishing from Google.

How to pass this test is an article for another time but at a minimum you should verify if your website passes.

Another important technical metric to worry about is a security protocol called SSL (Secure Sockets Layer). This changes the URL of a domain from http to https, and ensure the secure transmission of data. Any website that does not have SSL enabled will be penalized. While there are some exceptions to this rule, ecommerce and financial websites will be most heavily impacted.

Low cost webhosts charge an annual fee for SSL implementation, meanwhile good webhosts such as Siteground issue SSL certificates for free and automatically integrate them.

Meta Data

Another important element on the website is the Meta Title and Meta description. These content fields have an outsized order of importance that may contribute as much to the success or failure of a page as the entire content of that page.

This is because Google has a high probability of selecting the Meta Title and Meta description to showcase in the search results.  And this is why it is important to fill out the meta title and meta description field as carefully as possible.

The alternative is Google may choose to ignore the meta title and meta description to instead auto-generate data that it predicts will result in more clicks. If Google predicts poorly what title to auto-generate, this will contribute to less click-throughs by searchers and consequently this contributes to lost search engine rankings.

If Google believes the included meta description is optimized to receive clicks it will showcase it in the search results. Failing this Google grabs a random chunk of text from the website. Often Google selects the best text on the page, the problem is this is the lottery system and Google is consistently bad at choosing what description to select.

Of course if you believe the content on your page is really good, sometimes it makes sense to allow Google to pick the optimized meta description that best matches the user query. We will opt for no meta description for this article as it is content rich, and Google is likely to select a good description.

In the meantime, billions of humans are clicking on the best search results – This is the human-in-the-loop, Google’s last feedback mechanism – And this is where reinforcement learning kicks in.

What is Reinforcement Learning?

Reinforcement learning is a machine learning technique that involves training an AI agent through the repetition of actions and associated rewards. A reinforcement learning agent experiments in an environment, taking actions and being rewarded when the correct actions are taken. Over time, the agent learns to take the actions that will maximize its reward.

The reward could be based on a simple computation that calculates the amount of time spent on a recommended page.

If you combine this methodology with a Human-in-the-loop sub-routine this would sound awfully a lot like existing recommender engines that control all aspects of our digital lives such as YouTube, Netflix, Amazon Prime – And if it sounds like how a search engine should operate you are correct.

How Google Uses Reinforcement Learning

The Google flywheel improves with each search, humans train the AI by selecting the best result that best answers their query, and the similar query of millions of other users.

The reinforcing learning agent continuously works on self-improving by reinforcing only the most positive interactions between search and delivered search result.

Google measures the amount of time it takes for a user to scan the results page, the URL they click on, and they measure the amount of time spent on the visited website, and they register the return click. This data is then compiled and compared for every website that offers a similar data match, or user experience.

A website with a low retention rate (time spent on site), is then fed by the reinforcement learning system a negative value, and other competing websites are tested to improve the offered rankings. Google is unbiased, assuming there’s no manual intervention, Google eventually provides the desired search results page.

Users are the human-in-the-loop providing Google with free data and become the final component of the deep reinforcement learning system. In exchange for this service, Google offers the end user an opportunity to click on an ad.

The ads outside of generating revenue serve as a secondary ranking factor, floating more data about what makes a user want to click.

Google essentially learns what a user wants. This can be loosely compared to a recommender engine by a video streaming service. In that case a recommender engine would feed a user content that is targeted towards their interests. For example, a user who habitually enjoys a stream of romantic comedies might enjoy some parodies if they share the same comedians.

How Does this Help SEO?

If we continue with computational thinking we can assume that Google has trained itself to deliver the best results, and this is often achieved by generalizing and satisfying human biases. It would in fact be impossible for Google’s AI to not optimize results that cater to these biases, if it did the results would be sub-optimal.

In other words there is no magic formula, but there are some best practices.

It is the responsibility of the SEO practitioner to recognize the biases that Google seeks that are specific to their industry – And to feed into those biases. For example, someone searching for election poll results without specifying a date, are most likely searching for the most recent results – this is a recency bias. Someone searching for a recipe, most likely does not need the most recent page, and may in fact prefer a recipe that has withstood the test of time.

It is the responsibility of the SEO practitioner to offer visitors the results they are looking for. This is the most sustainable way of ranking in Google.

Website owners must abandon targeting a specific keyword with the expectation that they can deliver whatever they want to the end user. The search result must precisely match the need of the user.

What is a bias?  It could be having a domain name that looks high authority, in other words does the domain name match the market you are serving? Having a domain name with the word India in it may discourage USA users from clicking on the URL, due to a nationalism bias of trusting results that originate from a user’s country of residence. Having a one word domain may also give the illusion of authority.

The most important bias is what does a user want to match their search query? Is it an FAQ, a top 10 list, a blog post? This needs to be answered, and the answer is easy to find. You just need to analyze the competition by performing a Google search in your target market.

Black Hat SEO is Dead

Compare this to Black Hat SEO, an aggressive method of ranking websites that exploits devious SPAM techniques, including buying backlinks, falsifying backlinks, hacking websites, auto generating social bookmarks at scale, and other dark methodologies that are applied via a network of black hat tools.

Tools that are often repurposed and resold on various search engine marketing forums, products with next to no value and few odds of succeeding. At the moment these tools enable the sellers to become wealthy while they offer minimal value to the end user.

This is why I recommend abandoning Black Hat. Focus your SEO on viewing it from the lens of machine learning. It’s important to understand that every time someone skips a search result to click on a result buried underneath, it’s the human-in-the-loop collaborating with the deep reinforcement learning system. The human is assisting the AI with self-improving, becoming infinitely better as time progresses.

This is a machine learning algorithm that has been trained by more users than any other system in human history.

Google handles 3.8 million searches per minute on average across the globe. That comes out to 228 million searches per hour, 5.6 billion searches per day. That is a lot of data, and this is why it is foolish to attempt black hat SEO. Assuming Google’s AI is going to remain stagnant is foolish, the system is using the Law of Accelerating Returns to exponentially self-improve.

Google’s AI is becoming so powerful that it is conceivable that it could eventually become the first AI to reach Artificial General Intelligence (AGI). An AGI is an intelligence that is able to use transfer learning to master one field to then apply that learned intelligence across multiple domains. While it may be interesting to explore Google’s future AGI efforts, it should be understood that once the process is in motion it is difficult to stop. This is of course speculating towards the future as Google is currently a type of narrow AI, but that is a topic for another article.

Knowing this spending one second more on black hat is a fool’s errand.

White Hat SEO

If we accept that Google’s AI will continuously self-improve, then we have no choice but to give up on attempting to outsmart Google. Instead, focus on optimizing a website to optimally provide Google specifically what it is looking for.

As described this involves enabling SSL, optimizing page loading speed, and to optimize the Meta Title and Meta Description. To optimize these fields, the Meta Title and Meta Description must be compared to competing websites – Identify the winning elements that result in a high click through rate.

If you optimized being clicked on, the next milestone is creating the best landing page. The goal is a landing page that optimizes user value so much that the average time spent on page outperforms similar competitors who are vying for the top search engine results.

Only by offering the best user experience can a webpage increase in ranking.

So far we have identified these metrics to be the most important:

  • Loading Speed
  • SSL Enabled
  • Meta Title and Meta Description
  • Landing Page

The landing page is the most difficult element as you are competing against the world. The landing page must load quickly, and must serve everything that is expected, and then surprise the user with more.

Final Thoughts

It would be easy to fill another 2000 words describing other AI technologies that Google uses, as well as to dig deep further into the rabbit hole of SEO. The intention here is to refocus attention on the most important metrics.

SEO partitioners are so focused on gaming the system that they forget that at the end of the day, the most important element of SEO is giving users as much value as possible.

One way to achieve this is by never allowing important content to grow stale. If in a month I think of an important contribution, it will be added to this article. Google can then identify how fresh the content is, matched with the history of the page delivering value.

If you are still worried about acquiring backlinks, the solution is simple. Respect your visitors time and give them value. The backlinks will come naturally, as users will find value in sharing your content.

The question then shifts to the website owner on how to provide the best user value and user experience.
Location pages in Google’s crosshairs after October spam update

Within the last few months, service area business (SAB) websites started to see rank fluctuations aligned with the rollout of Google’s helpful content and spam updates around late August through October.

Chatter around those fluctuations picked up in the local SEO community during this period in various forums, including the Google SEO Mastermind Facebook group.

The common theme with sites that were impacted the most seemed to be related to duplicate content, specifically location pages – in other words, doorway pages.

However, sites weren’t getting directly penalized by rank. Instead, pages were being automatically deindexed, which in turn caused ranks to drop for queries related to the corresponding location pages.

Deindexing of location pages

Schieler Mew, admin of the Google SEO Mastermind group on Facebook, posted this video explaining what he saw with over 200 SAB sites.

In the video, he explains that sites with relatively low authority or a lack of helpful content throughout the site saw a deindexing of their “duplicate content” location pages en masse.

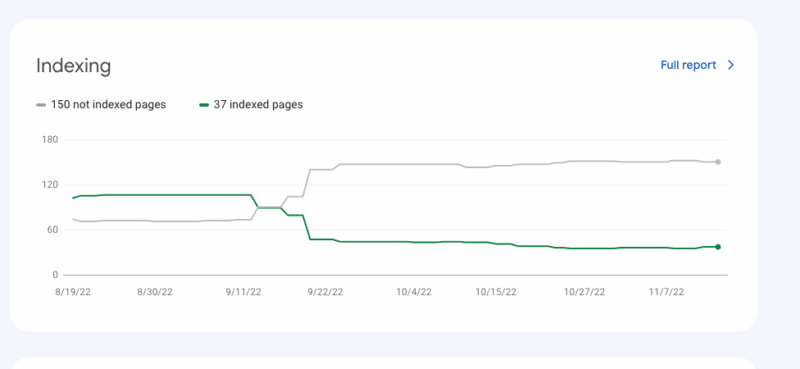
Scheiler and I jumped on a Google Meet, where he shared some data and screenshots below of what had happened in Search Console to these sites.

The first thing that was noticed was a large shift in the middle of September regarding indexed pages. This seems to line right up with the completion of the helpful content rollout.

GSC indexing issues

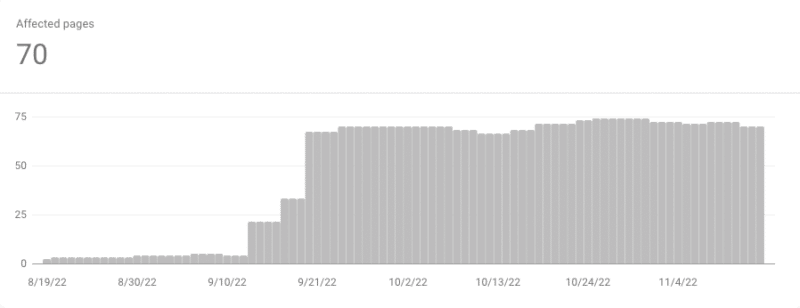
Digging into it, the next screenshot is all the pages that were deindexed seemingly overnight.

Finally, the report on the timeline of the affected pages.

The mass deindexing of pages that heavily contributed to geographic ranking vanished, taking the rankings with it.

This seemed to be the case for numerous other pages, although there were a few outliers.

Websites with seemingly higher authority or location pages that used unique content weren’t deindexed.

This leads me to believe that the helpful content and spam update algorithm seem somewhat unfinished. In this case, it tackled the easiest target – duplicate content location pages on sites with low authority.


Get the daily newsletter search marketers rely on.


How the helpful content and spam updates contributed

Most SEOs were under the assumption that these updates were targeting AI-generated content. (Recall that in an office-hours hangout in April, John Mueller referred to it as “spam” and made it clear it was against Google’s policies.)

On November 7, Danny Sullivan squashed this in a tweet, stating:

  • “We haven’t said AI content is bad. We’ve said, pretty clearly, content written primarily for search engines rather than humans is the issue.”

This is when I started putting two and two together.

SAB sites are dropping in rank right around the rollout of both the helpful content and spam updates, and we know it’s primarily targeting pages that have content written for search engines rather than humans.

What kind of pages would a local SAB have that almost every SEO in the industry creates?

Location pages.

Understanding doorway pages

A doorway page is essentially what Danny Sullivan was talking about in the above tweet. It’s a page written to rank for a specific keyword but provides little to no value to a user.

An example of doorway pages in the local SEO industry is location pages. In other words, a page that exists for the sole purpose of ranking [city #1] + [service A] multiplied by the number of cities and/or services the business is trying to rank for.

These can be created faster if the content is duplicated and only the keywords are swapped out. Additionally, you can write custom content for each page, but it’s still a doorway page.

SEOs in this sector hate to admit it, but location pages are doorway pages. Mueller confirmed this in February.

Doorway pages have always been against Google’s policies, but there had never seemed to be a way to suppress these algorithmically.

The only punishment seemed to be manual actions, and until this year, SABs seem to have been put on the Google backburner – so no one really ever saw any consequences for doing this.

Recent Google updates to local SEO

In the last few months, waves have been made within the local SEO community, not just with doorway pages, including:

For the most part, Google has addressed a few of these issues, such as the suspended business profiles and reviews hovering in purgatory – usually giving credit to “bugs.”

At some point, SEOs have to ask themselves why suddenly there are so many bugs in a specific sector.

Aside from the bugs with GBP profiles, Google has also made some obvious and strict changes to how profiles are now verified.

It started with the default verification method switching from postcard to video. Then, in some instances, video being the only way to verify.

This, mixed with business profiles suddenly being suspended over minor issues, started to raise flags that Google was finally tackling the SEO spam in the SAB community.

Fast forward to September this year, SEOs in communities and forums started to see declining rankings for location-dependant keywords and pages.

All of this being said, it looks like Google is seriously cracking down on local businesses that are violating their spam policies.

Can location pages still work?

The short answer is, “yes”, but it’s only a matter of time before location pages fade into archaic SEO practices like hidden text or meta keyword stuffing.

Google deindexing duplicate content location pages is just the first step in the conquest to punish sites for using doorway pages that don’t benefit humans.

It’s unclear whether or not Google will institute rank penalties for doorway pages in the future or continue to not index the pages.

My theory is that this is a temporary fix. Location pages are something local SEOs should be leaving in the past.

At the end of the day, Google wants content to exist to provide a positive user experience, not to influence rank.

As a consumer, I’ve never found a location page to benefit my user experience. This is how we should think when creating pages and content.

First, think about how it can help the user and then how it can be optimized to help your rank – in that order.

Alternative optimization options to rank in nearby cities

Suggesting that location pages may be coming to an end isn’t cause for local SEOs to throw their hands up on optimizing for neighboring cities and areas.

There are alternative things we can do that put the purpose of the content back in the direction of helping humans first.

Target your primary service area in your H1s and page titles

Chances are you or your client have a number one area they want to target.

Make sure this city is mentioned in your H1s and page titles. This will make it clear to Google from a content standpoint where your primary area of service is.

Make sure to have a general service area page

Make sure to have a general page that tells users where you or your client serves.

List out all counties, cities, or neighborhoods and include a map that visualizes that service area.

Create project pages

This is my favorite. If you or your client have project-oriented work like landscaping, roof repair, construction, etc; create pages for specific projects that were completed.

Treat it similarly to a blog or gallery. Add before and after pictures, explaining the job or project details.

Mention what city it was located in, how much it cost, some challenges, etc.

This method will not only show potential customers what your company is capable of and the type of work you do, but it’s also a great way to rank your service and the city where it was performed.

An example of a project page for a landscaper could be titled “Modern Highland Stone Retaining Wall in Minnetonka, MN.”

Local newspaper press releases

Reach out to local newspapers in the surrounding areas and issue a press release.

Brag about your company regarding a past or upcoming charitable contribution or discount you give. Newspaper and local publishing sites typically link back to your website.

Join multiple local Chambers of Commerce

These typically have an annual fee associated with each one you join, but each city you or your client is targeting has one.

If it’s in your budget, join them for the location-relevant links and geographic authority.

Where do we go from here?

Google’s enforcement of service area businesses is long overdue, but it seems like the action is now being taken. 

Some location pages still work as long as the site has high authority and good overall content. It’s duplicate content location pages that are getting deindexed.

Overall, SABs are now under Google’s magnifying glass. If SEOs aren’t getting hit with penalties yet, I would put money on it being something that will be happening in the very near future.

It’s important to remember that Google is always evolving. Even though something like unique content may still work for location pages, I bet that Google will tackle this next.

Google’s SpamBrain AI is updated every now and then. This time, it may be evolving to target easily distinguishable doorway pages.

It’s only a matter of time before it understands a location page as a standalone doorway page with unique content.

As SEOs, we must review our local business sites, stick to the core principles of local search,  and do some housekeeping per Google’s policies – before their algorithm team pays us a visit. 


Opinions expressed in this article are those of the guest author and not necessarily Search Engine Land. Staff authors are listed here.


New on Search Engine Land

About The Author

Jake Hundley

Jake Hundley is the founder and co-owner of Evergrow Marketing, a digital marketing agency that focuses on the lawn care and landscaping industry. His background and strengths lie primarily in digital strategy, PPC, and SEO, specifically local SEO. Jake also consults with enterprise companies leveraging their first-party data utilizing CDPs as a Client Partner Manager with Leverage Lab.

Google’s John Mueller: “Search Is Never Guaranteed”

Google Lookup Advocate John Mueller claimed, “search is hardly ever certain,” in reaction to a site owner asking why their information isn’t indexed.

In the r/TechSEO discussion board on Reddit, a person is dissatisfied that a web site re-publishing identical content material is having indexed quicker.

The Reddit consumer posts a thread asking if they can use the Indexing API to brute pressure their way into Google’s index.

Mueller shoots that strategy down, expressing the Indexing API is reserved for unique kinds of material, this sort of as livestreams and job postings.

He follows up with the assertion that search is not guaranteed and delivers insight into what Google prioritizes about indexing.

Mueller On What Can make Content well worth Indexing

Mueller has earlier said web pages want to be worthwhile to be indexed, and he shares that sentiment once more on Reddit.

Additional, Mueller goes about several standards Google’s algorithm appears to be like for when thinking about irrespective of whether the articles is well worth indexing:

“Search is under no circumstances confirmed, and there are tons of websites that are seeking to drive their updates into Google. I feel what ultimately is effective best is that you demonstrate to Google (and customers) that the updates you’re furnishing are precious: exclusive, powerful, high-excellent, and not one thing that’s already published elsewhere.”

For context, the Reddit person runs a website that publishes obituaries.

In the upcoming aspect of his reaction, Mueller acknowledges it can be demanding to guarantee written content contributed by other people today satisfies Google’s requirements.

That place cannot be overstated about obituaries when Google Search is the very last detail folks think about.

Nevertheless, the full web-site is in the Reddit user’s regulate, and they are not minimal to publishing contributed articles.

Mueller tells the web site proprietor to believe of means to make their web page much more worthwhile, expanding the probability that Google indexes internet pages swiftly.

“I realize that is tough when it arrives to person-generated articles (which I suppose some of this will be), but in the end your web-site is what you publish, regardless of where by it initially arrives from. So the additional you can do to make certain the indexable written content on your web page is quickly findable and considerably beneficial to the world-wide-web, the more possible Google will be in a position to select it up swiftly (and that can suggest that you block content material that you identify is much less-valuable from being indexed, for case in point).”

When Google indexes re-revealed content more quickly than the primary variation, it perceives the source’s web page as fewer useful than the website copying its content.

There’s no easy option to that problem, such as applying Google’s Indexing API. The Reddit consumer will have to make modifications to their site to verify it’s value finding crawled and indexed speedier.

That reported, Mueller implies a slight adjust all web sites can make to sign to Google there’s new material offered.

Linking to new internet site information from the property page can get it on Google’s radar more quickly, Mueller suggests:

“One of the points even smaller, newer web sites can do is to point out and backlink to updates on their homepages. Google ordinarily refreshes homepages additional usually, so if there’s some thing vital & new, make positive you have it there. A lot of web sites do this intuitively, with a sidebar or a portion for updates, mentioning the new headlines & linking to the written content.”

When that will assist get content discovered faster, there is nevertheless no warranty Google will index it additional speedily.


Supply: Reddit
Showcased Image: JHVEPhoto/Shutterstock